---
title: "The SQL Injection Sat Below 188 Test-Suite Findings"
author: "Harry"
published: 2026-11-02T01:59:24.811Z
category: "Security Testing"
tags: ["ai-sec"]
canonical: "https://fxblog.dev/posts/security-scan-report-could-not-evaluate"
---
# The SQL Injection Sat Below 188 Test-Suite Findings
## Key takeaways
- Scanning OWASP Juice Shop produced 246 findings, 188 of them hardcoded credentials in the test suite, and severity order put seed passwords above the SQL injection in the login route.
- An ai-sec report has four parts: the verdict, the findings, the non-application block and Could not evaluate.
- Every finding has a severity, how bad it is, and a confidence, how sure, and Certain needs a reproduction by someone other than the tool that found it.
- Findings in test, fixture, example, generated or vendored code are capped at Tentative, grouped and counted, and never fail a build on their own.
- On Juice Shop, sec modules grades 9 modules measured, 3 partial, 1 blind and 1 no-engine, and a grade should be quoted with the module.
> **TL;DR** A security scan report sorted by severity can bury the one defect that matters under findings from your own test suite. ai-sec's report is built to be read in four parts, and it never lets a fixture fail the build. Only here: a finding in test, fixture, example, generated or vendored code is capped at `Tentative`, grouped into one counted block and kept out of the verdict, and every module carries a grade that says what its result is worth.
>
> **Do this:** In your next security scan report, read `Could not evaluate` first, the non-application block second, and the findings last.
[Part 1](01-ai-security-assessment.md), **When Zero Findings Means Nothing Was Read**, ended with OWASP Juice Shop's M2 row honestly `blind`. The same scan returned 246 findings, and the SQL injection in the login route was not on the first screen. This part reads that report the way it was built to be read.
The scan of Juice Shop, read-only at T0, produced 246 findings. 188 of them were hardcoded credentials in `test/`. Because `Critical` sorts above `High`, the first three screens were `data/static/users.yml` seed passwords and `test/api/2fa.test.ts`.
**This series, in three parts:**
1. **When Zero Findings Means Nothing Was Read**
2. **The SQL Injection Sat Below 188 Test-Suite Findings** (you are here)
3. **Grade Your Security Scanner Against Answers It Didn't Write**
## Four parts, in this order on purpose
1. **The verdict**, against a severity bar, for example `FAIL — 3 finding(s) at or above the bar (High)`.
2. **The findings**, each with two axes.
3. **The non-application block**: reported, counted, kept out of the bar.
4. **`Could not evaluate`**: every gap, and how to close it.
> **Tip**
>
> If you read one section of a report, read the fourth. A run that passes with a non-empty ledger says so on its first line.
## Severity says how bad. Confidence says how sure
`High / Tentative` and `High / Certain` are different jobs: the first needs someone to look, the second needs someone to fix. Severity is rescored in context, never copied from the tool, and when two scanners disagree the report says so.
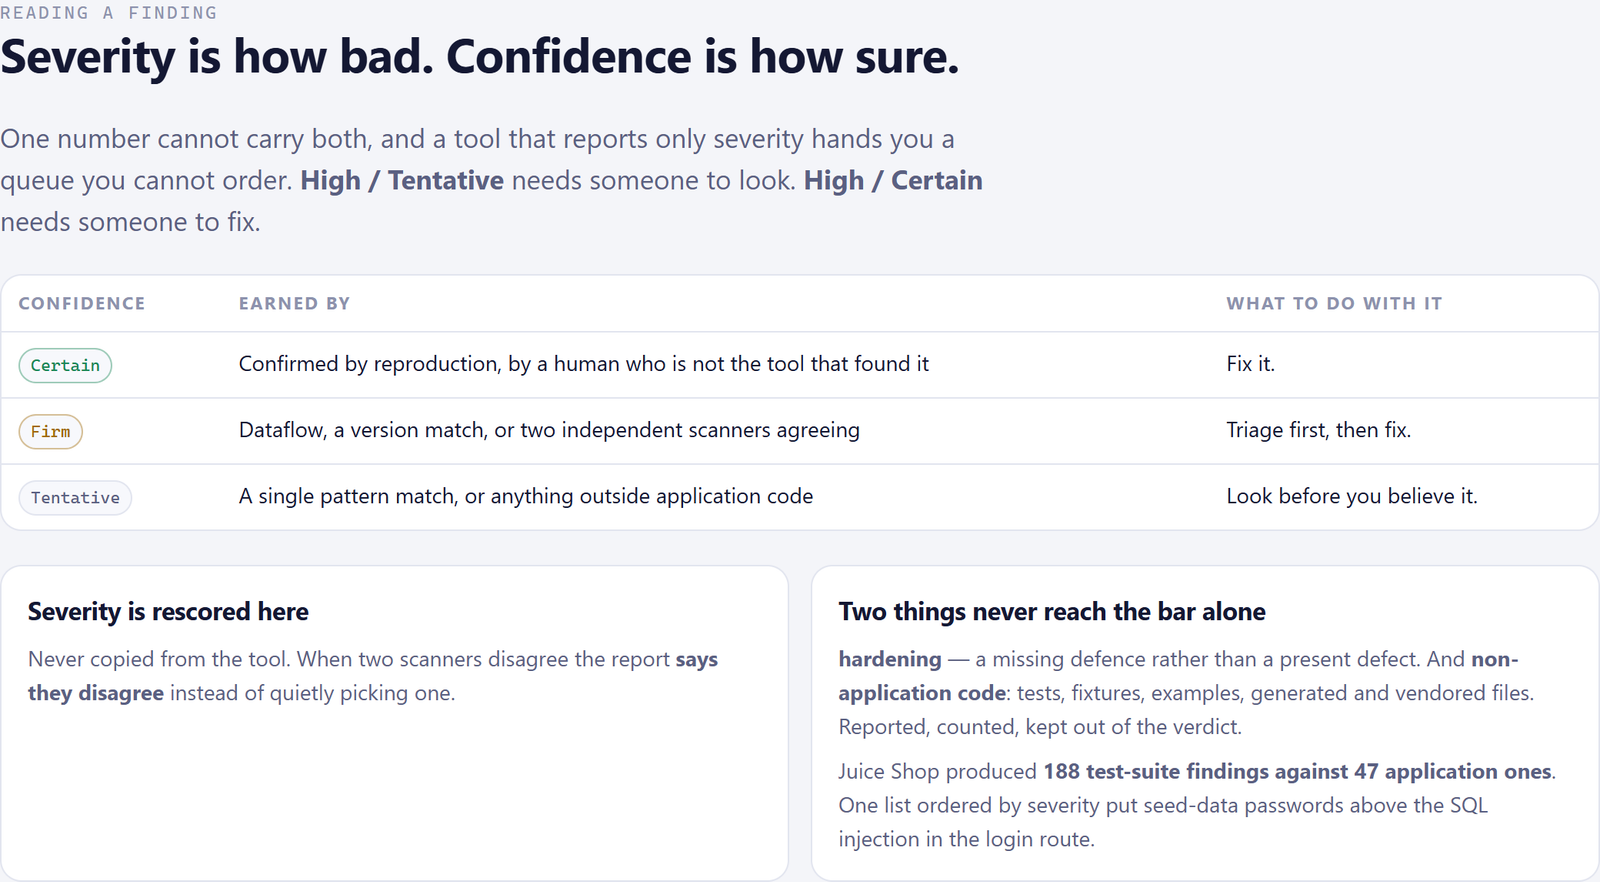
_Certain needs a reproduction by someone who is not the tool that found it_
Findings from several scanners merge by CWE family, not rule id, so `open-redirect` and `javascript.express.security.audit.express-open-redirect` are one finding with two sources.
## The test suite is reported, not counted
Every one of those 188 findings really was in that file. The report was accurate and nobody would have read it, which is worse than a false positive: a false positive gets argued with.
So every finding is now labelled `application`, `test`, `fixture`, `example`, `generated` or `vendored`, and the rest are grouped:
```text
In non-application code (189) — reported, not counted against the bar
generated: Regular expression open to catastrophic backtracking ×1
test: Hardcoded credential ×184, Regular expression open to catastrophic backtracking ×3, Unpinned base image ×1
a credential in a test file is still a credential — judge these, do not assume the path makes them safe
```
Nothing is dropped. A credential in a test file can be a live one, and a rule that deleted it would be the leak. When a path matches no known shape, I made it classify as `application`: calling a handler a test hides a real finding, while calling a test a handler only costs attention.
## Then ask what each module's zero is worth
`sec modules` grades all fourteen modules against a benchmark with recorded answers. On Juice Shop:
```text
3 partial · 1 blind · 9 measured · 1 no-engine
```
Which grade a module gets
```mermaid
flowchart TD
A{any engine for it?} -- no --> N[no-engine]
A -- yes --> C{planted defects
to score?}
C -- no --> D0{capability blind?}
D0 -- yes --> BL[blind]
D0 -- no --> U[unmeasured]
C -- yes --> B{capability blind
and a defect missed?}
B -- yes --> BL
B -- no --> D{found how many?}
D -- none --> F[failing]
D -- some --> P[partial, misses named]
D -- all --> M[measured or self-measured]
```
Quote the grade with the module. "M5 found nothing" means something different when M5 is `measured` and when it is `unmeasured`. M11, business logic, stays `no-engine` on every run: an automated M11 that finds nothing would be worse than saying so.
## Twelve layers of thirty-two
The coverage map lists thirty-two security layers and who owns each. Twelve are covered and graded for the product being scanned. ZAP and nuclei are built but blocked on this machine. Privacy and PII data-flow is covered by nothing, and that is the gap most likely to matter legally.
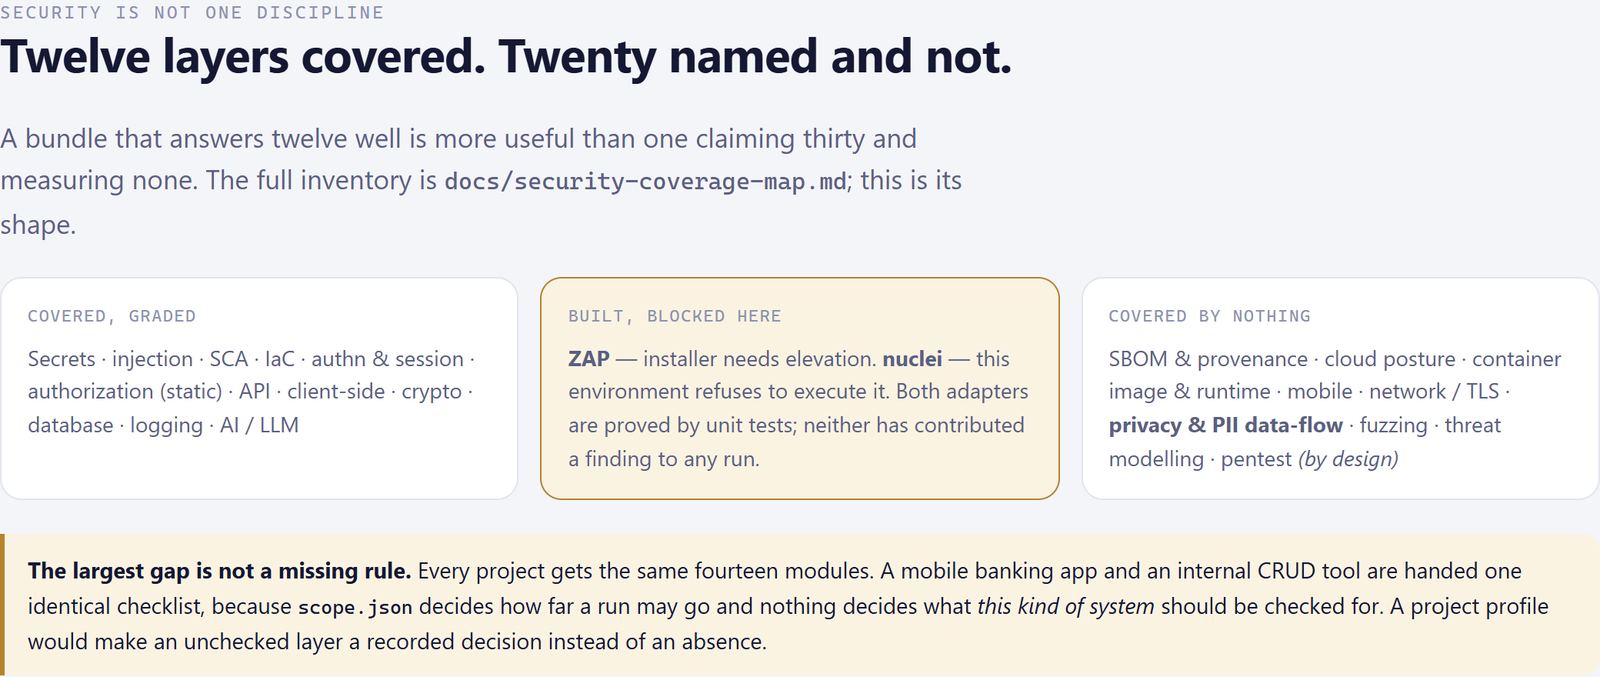
_Every project gets the same fourteen modules, which is itself the largest gap_
## Try it
```sh
node bin/sec.mjs scan . --baseline .sec/default/baseline.json
echo $?
```
| exit | meaning |
| ---- | --------------------------------------------- |
| 0 | done · PASS · WARN |
| 1 | error, or FAIL |
| 2 | refused: a gate said no |
| 3 | not evaluable: nothing produced coverage |
| 4 | degraded: something ran and something did not |
Treat 4 as a warning you investigate, not a pass. On Juice Shop, nine modules read `measured`: full marks on a corpus nobody here wrote. Whose answers were those, and what did the first run score before any rule was added? Part 3, **Grade Your Security Scanner Against Answers It Didn't Write**, opens the answer keys.
## Read this with your AI
```text
Read the post "The SQL Injection Sat Below 188 Test-Suite Findings".
1. Summarise it in 5 bullets for an engineer who triages security scan reports.
2. Ask me 3 questions to check I understood; wait, then correct me.
3. Take my last scan report and sort its findings into application and non-application code.
```
> **Success**
>
> You can read a security scan report for what it skipped, where its findings live and what each module's grade is worth. Next: **Grade Your Security Scanner Against Answers It Didn't Write**.
## FAQ
### Why not just drop findings in test files?
A credential in a test file can still be a live credential. ai-sec reports and counts those findings in one block and keeps them out of the verdict, so nothing is deleted.
### What does exit code 4 mean in CI?
The run was degraded: something ran and something did not. It is not a pass; you did not get the scan you asked for.